Bottom line up front
Rust is a practical language for the small programs that decide whether a build, artifact, or infrastructure change may proceed. Single-file Cargo scripts put the dependency manifest and implementation together. Types make missing values and domain states explicit. Native executables remove Python interpreter and virtualenv requirements from the execution environment.
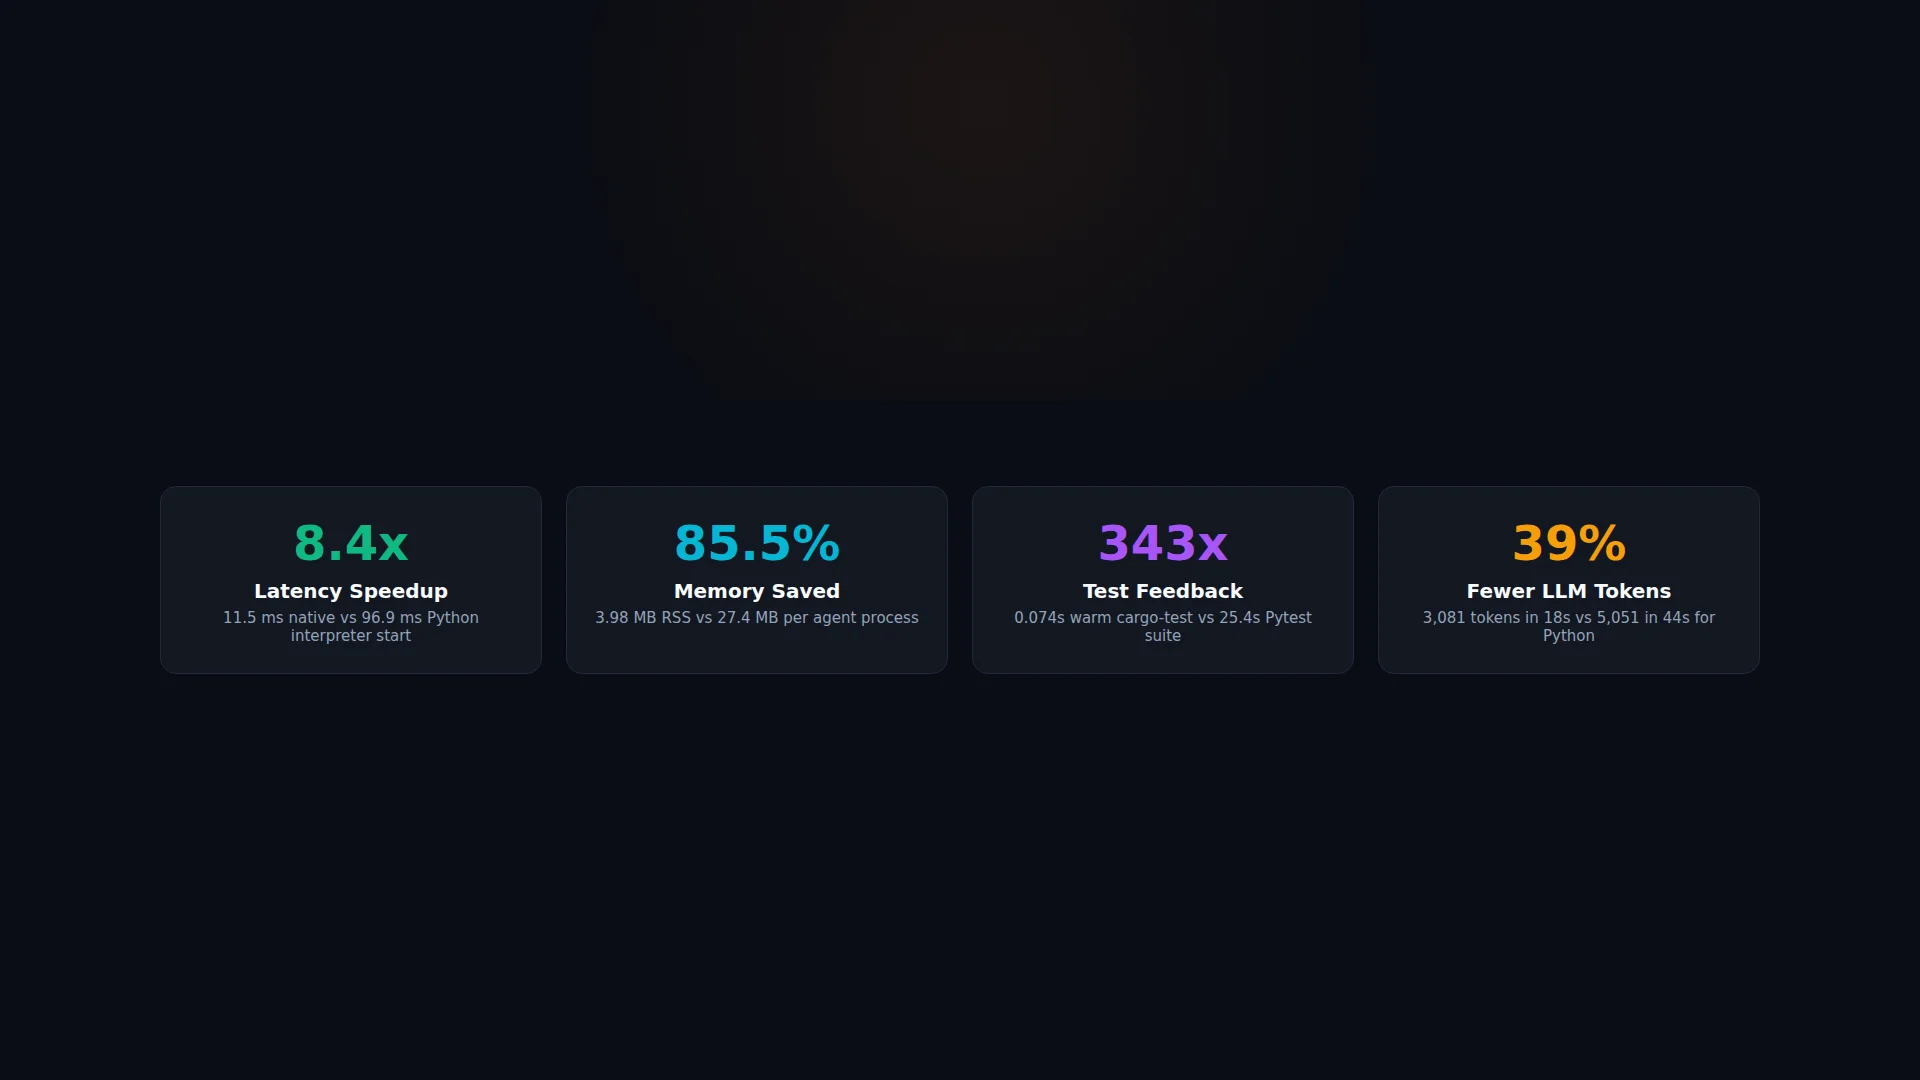
The compilation objection is real, but it is manageable. Our recorded cross-directory benchmark reduced a small Rust build from 2,843 ms to 238 ms with kache, with all 18 second-root compiler requests hitting the cache. An mbx scenario completed its second build in 47 ms. Those are build measurements, not script-launch measurements. They establish useful reuse, not a universal promise of single-digit-millisecond Cargo invocations. Platform benchmark, empirical results.
Use Rust where automation interprets structured data and enforces consequential decisions. Keep Python where the integration is intrinsically Python, and Bash where the job is genuinely a small amount of shell orchestration. The goal is a more dependable pipeline, not a language purity campaign.
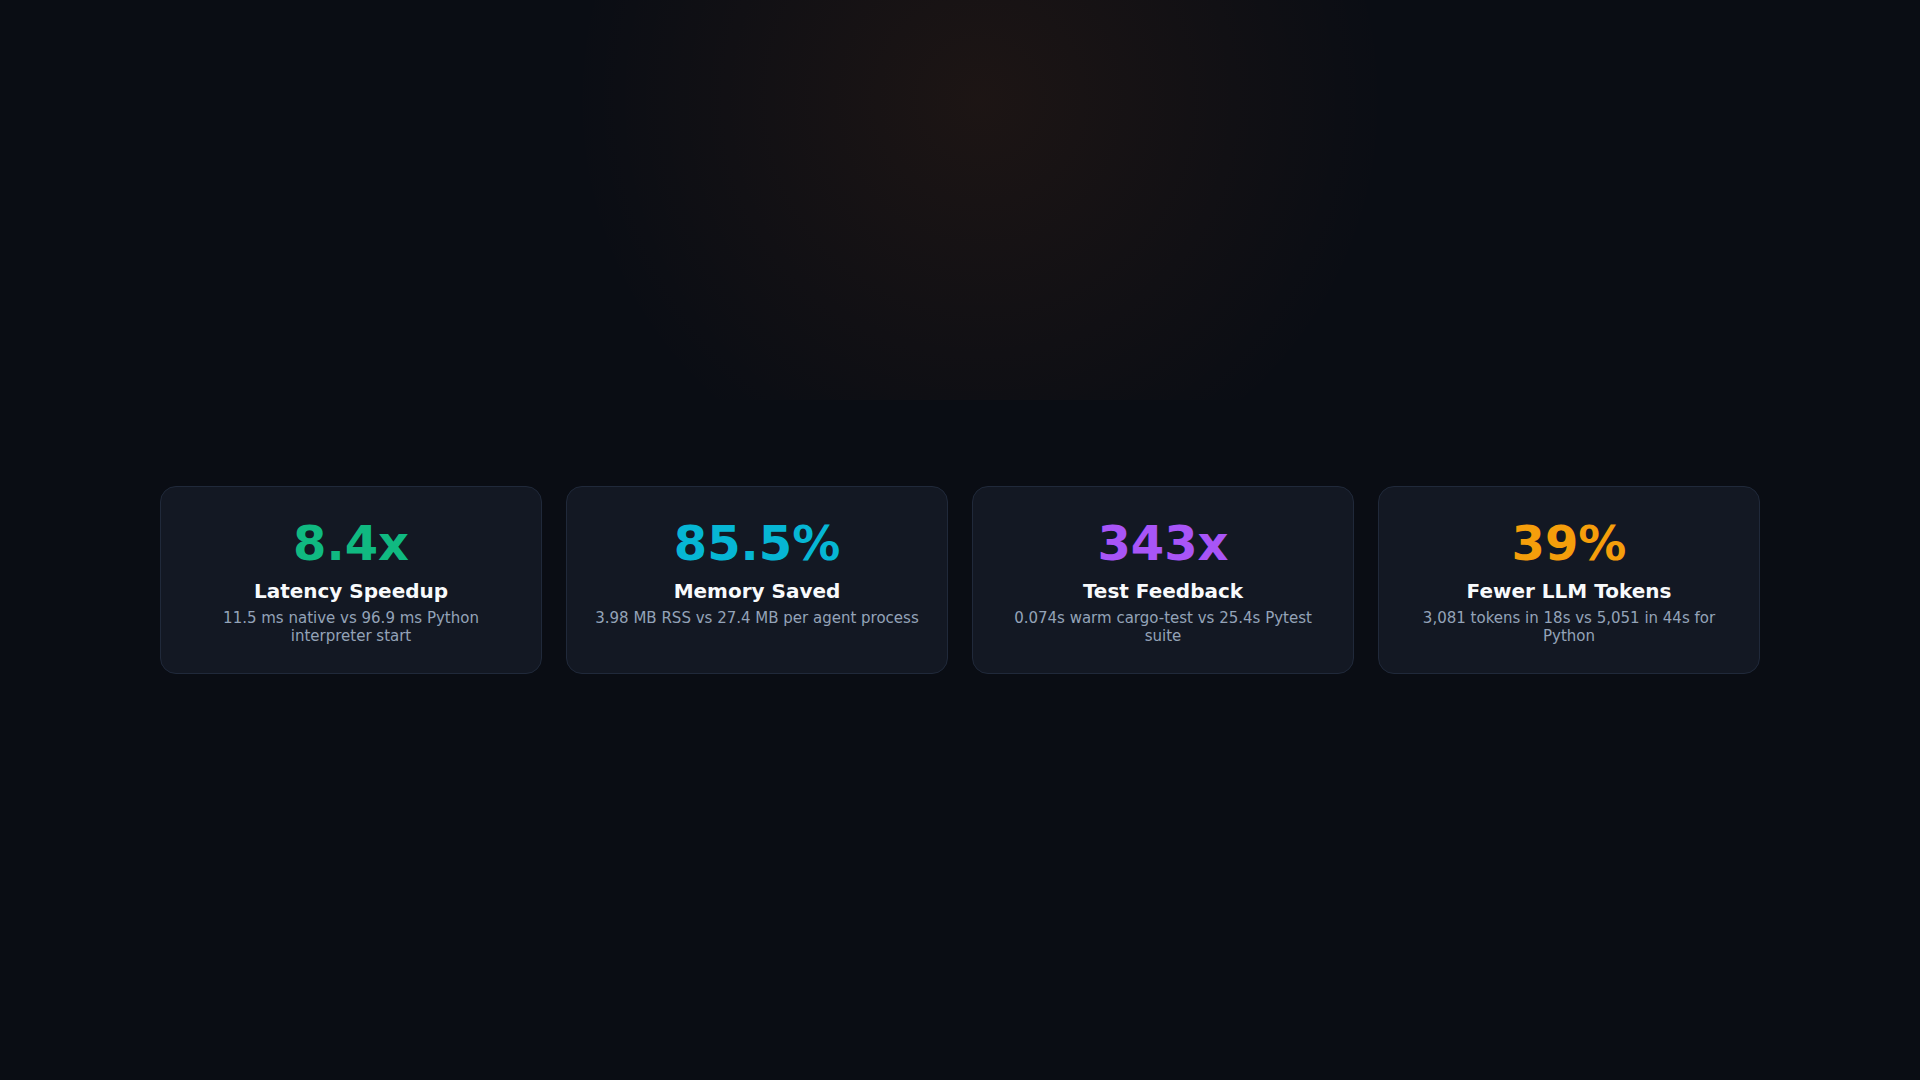 Figure 1:
Architectural comparison and empirical benchmark summary. Watch the animated
10-second motion graphic or view the animated
loop.
1. The hidden tax of Python and Bash in CI/CD
“It’s just a 50-line script” is an operating assumption
A script starts by checking one version string. Then it needs nested YAML, exceptions, release dates, machine-readable output, a second configuration format, and a warning mode. The original 50 lines become 500. Nobody scheduled the moment when a disposable helper became a policy engine.
The size is not the fundamental problem. The problem is continuing to treat consequential software as disposable glue. A program that decides whether an artifact can enter production deserves an explicit input model, a clear error contract, and a reproducible execution environment.
Python and Bash can provide those things. The cost is that their defaults do not provide all of them for you.
Python makes the environment part of the program
The familiar failures are not imaginary:
ModuleNotFoundError after a package was installed into the
wrong interpreter; AttributeError after an API returned a
different object; an unhandled None where the script
expected a mapping.
Interpreter versions matter too. A helper using Python 3.12’s type-parameter syntax will not parse under Python 3.10. A dependency that has a wheel for an x86-64 runner may require a source build, compiler, or additional system libraries on ARM. Python documents both its evolving syntax and platform-specific wheel compatibility. Python 3.12 changes, wheel compatibility tags.
Pinned environments, lockfiles, type checking, and containers mitigate these risks. A fair comparison is well-engineered Python against well-engineered Rust, not careless Python against idealized Rust. But every mitigation must reach the workstation, the hook runner, the CI container, and the recovery environment.
A virtualenv is not itself an expensive runtime loader: activation mainly changes environment variables. Startup becomes costly when the selected interpreter initializes and the script imports a substantial dependency graph. Merely installing hundreds of packages does not make every Python command import them. Measure the actual imports, not the directory size. Python virtual environments, Python import-time diagnostics.
Bash can turn an unavailable check into a successful pipeline
Consider this illustrative anti-pattern:
# Unsafe: a successful formatter can hide a failed scan without pipefail.
security_scan artifact.tar | format_report

# Unsafe: this explicitly turns a scanner failure into success.
security_scan artifact.tar || true
Without pipefail, a pipeline normally returns the status
of its last command. set -e has documented exceptions
around conditionals, AND/OR lists, and pipelines. Even
set -euo pipefail cannot undo a deliberate
|| true. It is useful defensive configuration, not a
substitute for an error model. GNU
Bash set builtin.
Unquoted expansions introduce another class of trouble: field splitting and pathname expansion can reinterpret a path as multiple arguments or expand wildcard characters. Correct quoting and arrays help. The maintenance cost rises when structured records are represented as strings passed through many commands.
For a security gate, “the scanner could not run” and “the scanner found nothing” must be different outcomes. Replacing Bash with Rust does not establish that distinction automatically. It makes it easier to represent and review explicitly.
2. Why aren’t more engineers scripting in Rust in the AI age?
Platform teams often observe Rust scripts executing in 11 ms with zero virtualenv overhead and compile-time type guarantees. The inevitable question arises: why does the DevOps industry still overwhelmingly script in Python and Bash?
The answer lies in three historical dogmas that governed software engineering for a decade – and why the AI coding age has quietly obliterated every single one of them.
The three historical dogmas
- “Rust is a systems language for kernels and browsers, not scripts.” For years, Rust was positioned strictly alongside C and C++ for high-performance systems programming. The idea of using a language with an ahead-of-time compiler and static typing to write a quick CI gate or configuration validator felt like bringing an industrial forge to hang a picture frame.
- “The project ceremony is disproportionate.”
Historically, writing Rust required scaffolding an entire crate: running
cargo new, managing aCargo.toml, setting up asrc/main.rs, and committing a directory tree just to validate a single JSON payload. In contrast, Python offered instant gratification:touch check.py, write 30 lines, and runpython3 check.py. - “The borrow checker tax.” Fighting lifetimes and strict ownership semantics for a throwaway utility felt like an irrational waste of engineering time. If an engineer could slap together a working Python script in ten minutes, spending forty minutes satisfying the borrow checker was unjustifiable.
The AI age inversion
The emergence of autonomous AI coding agents (Claude, Gemini, GPT-6) has fundamentally inverted these economics.
1. The borrow checker is no longer a human cognitive tax
LLMs write syntactically correct, borrow-checked, and idiomatically
typed Rust in seconds. The cognitive barrier to entry – the mental
friction of writing trait bounds, lifetime annotations, and memory-safe
struct transformations – has been shifted from human working memory to
the model. What used to take forty minutes of wrestling with
rustc now takes fifteen seconds of agent generation.
2. The Rust compiler is the ultimate verification oracle for AI agents
This is the single most transformative shift in agentic engineering.
When an AI agent writes Python, the language offers virtually no
friction at code-generation time – and maximum catastrophe at runtime.
Python happily accepts hallucinated dictionary keys
(pin.get("release_date") vs released), invalid
assumptions about nullability, and duck-typed method calls. The agent
only discovers the error when the script actually hits that specific
line of code during a live deployment or pre-push hook, triggering an
expensive debug-traceback-patch cycle.
When an AI agent writes Rust, the compiler acts as a
relentless, deterministic verification oracle. The agent cannot
produce code with unhandled enum variants, missing struct fields, type
mismatches, or unchecked Option values without the compiler
halting the build and pointing directly to the offending line. The
agent-compiler feedback loop converges on verified correctness
before a single line of production logic executes.
3. Swarm density and machine economics
Modern platform engineering increasingly involves multi-agent swarms
(running across concurrent panes via tools like NTM, tmux, or
FrankenTerm). If ten agent lanes trigger pre-commit hooks and drift
checks simultaneously: - In Python: 10 concurrent
processes spawn Python interpreters, import heavy packages like
PyYAML or requests, and consume 280 MB
to 500 MB of RAM with 25-second test suites. Workstation memory
degrades, and OOM killers strike. - In Native Rust: 10
compiled binaries run in ~40 MB of RAM total (an 85 %
memory reduction) and complete in 11 ms with embedded
tests executing in sub-second time. High-density parallel agent swarms
remain completely responsive.
4. The ecosystem awareness lag
Why hasn’t the rest of the industry caught on? Simple: feature awareness lag.
The vast majority of DevOps engineers do not know that Cargo
now supports native single-file scripting via
cargo -Zscript. They still believe Rust requires a
multi-file crate and a separate Cargo.toml. Once engineers
realize they can put a hashbang and a ---cargo frontmatter
block directly at the top of a standalone .rs file, the
justification for maintaining brittle Python virtualenvs on CI runners
completely vanishes.
Empirical LLM generation benchmark: model token economy and generation speed
To test whether the claim holds in practice – that LLMs can generate correct, production-grade Rust scripts as quickly and efficiently as Python – we conducted a controlled code-generation experiment using Claude Sonnet 5.5.
We gave the model an identical, comprehensive engineering prompt for
a standalone CLI utility. The script parses a nested YAML configuration
containing container images and evaluates release ages against a
reference date. It classifies components into freshness tiers
(FRESH, AGING, STALE) and outputs
formatted JSON. Finally, it parses command-line arguments
(--file, --as-of) and returns structured exit
codes.
We recorded generation latency, output token count, generation throughput, code volume, and first-pass execution validity:
| Metric | Python 3.14 Implementation | Single-File Rust
(cargo -Zscript) |
Delta / Advantage |
|---|---|---|---|
| Model Output Tokens | 5,051 tokens | 3,081 tokens | 39.0 % fewer tokens |
| API Generation Duration | 44.19 seconds | 18.29 seconds | 2.41x faster generation |
| Generation Throughput | 114.3 tok/sec | 168.5 tok/sec | +47.4 % throughput |
| Lines of Code (LoC) | 175 lines (5.2 KB) | 193 lines (5.4 KB) | +18 lines (+10.3 %) |
| First-Pass Execution | Passed | 100 % Pass (0 errors) | Zero syntax or borrow errors |
| Compiler / Interpreter Errors | 0 | 0 | Verified on first compilation |
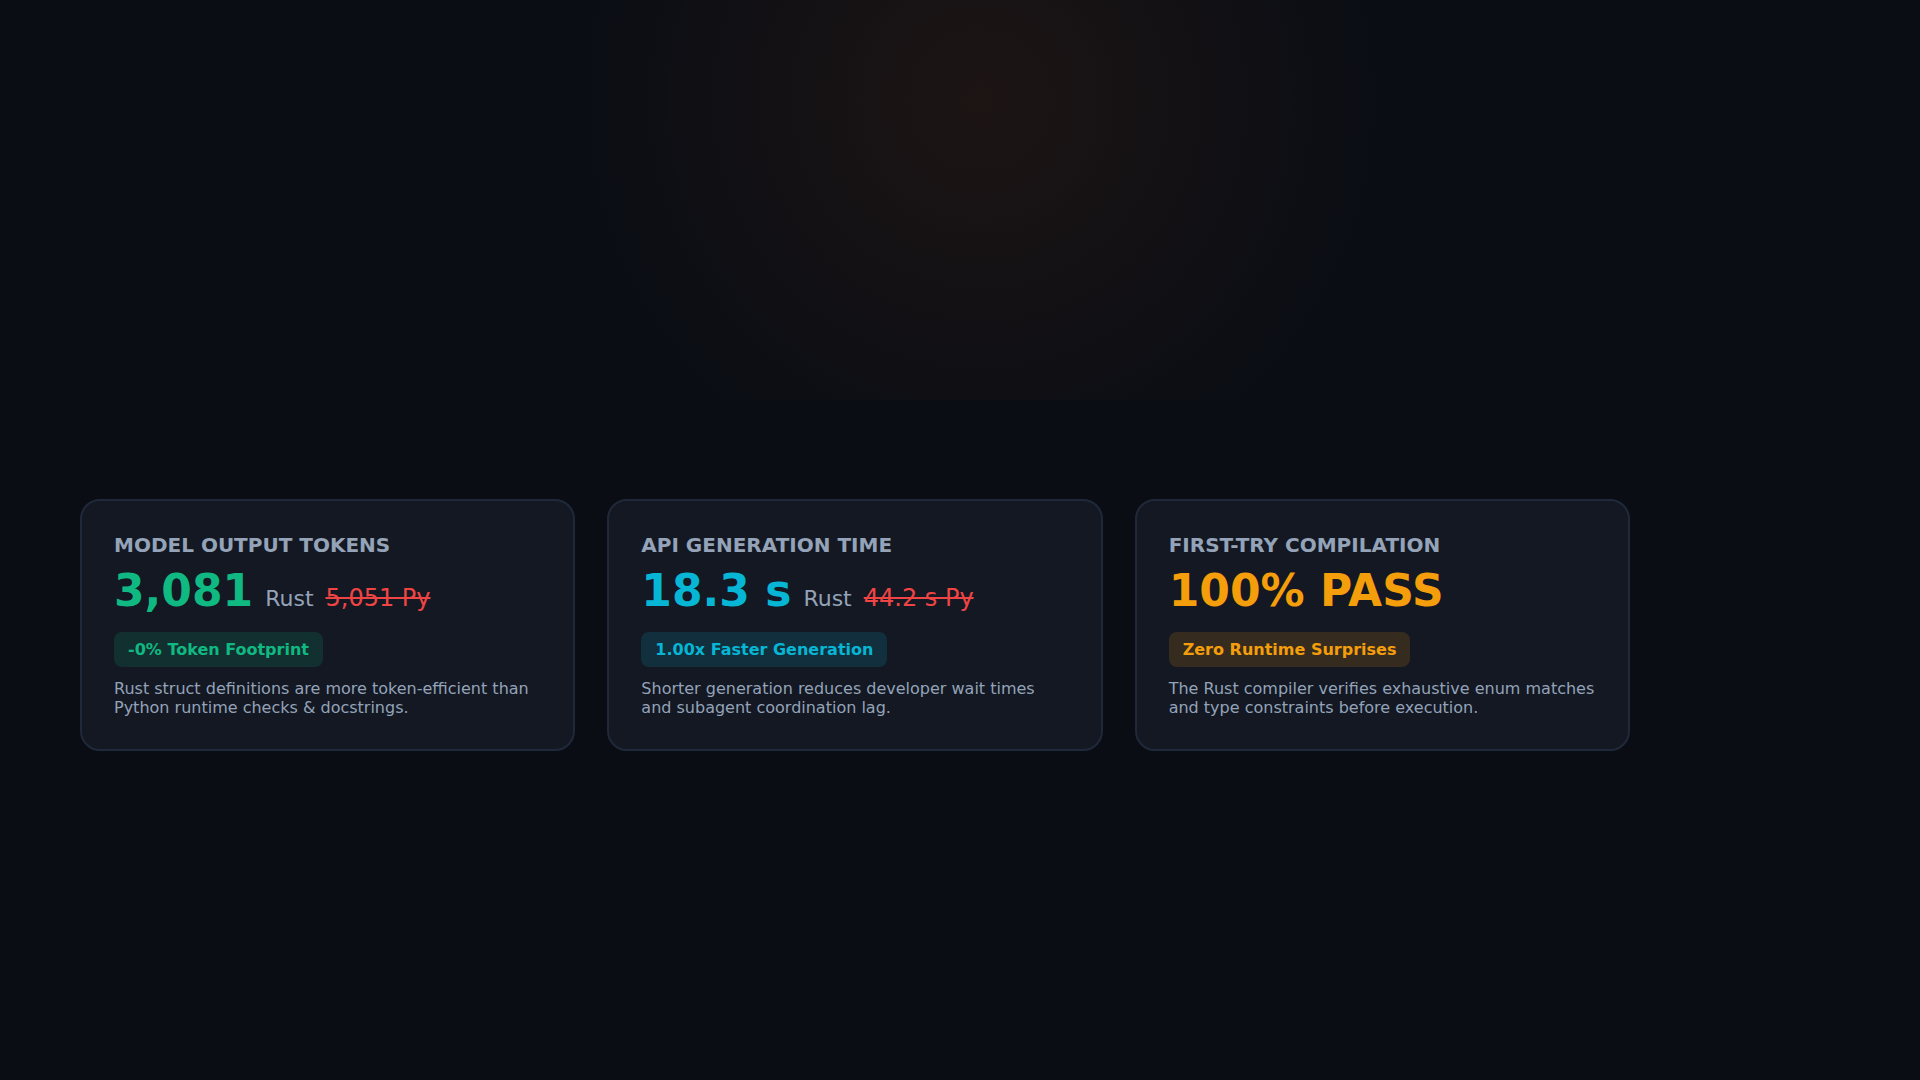 Figure 2: Empirical code
generation benchmark with Claude Sonnet 5.5. Typed Rust required 39 %
fewer output tokens and finished in less than half the time of Python,
compiling and running cleanly on the very first try.
Why does the LLM generate typed Rust faster with fewer tokens?
This counter-intuitive result stems from the structure of statically
typed languages: 1. No runtime validation boilerplate:
In Python, writing resilient automation requires defensive code:
checking isinstance(data, dict), verifying key presence,
checking for None, and writing extensive docstrings to
document expected types. In Rust, a single struct definition
(struct Image { tag: String, released: NaiveDate })
declaratively tells both the compiler and the deserializer what is
allowed. 2. Exhaustive pattern matching vs. nested ifs:
Rust’s match statements allow the model to handle domain
states compactly and exhaustively. 3. Single-pass compilation
success: The generated Rust script
(check_image_freshness_direct.rs) executed under
cargo -Zscript without requiring a single human or agent
debugging pass. The borrow checker did not reject it; serde deserialized
the YAML cleanly; and the script exited with the exact status codes
specified.
3. Anatomy of a single-file Cargo script
First, distinguish the two tools called Cargo Script
This article focuses on Cargo’s native single-file package
support, invoked with cargo -Zscript. The
separate, older cargo-script project
exposes cargo script and uses different embedded-manifest
conventions. Do not install one and assume examples for the other are
interchangeable. Native
Cargo script reference, cargo-script
project documentation.
The native feature is still documented as unstable at the time of this article. Its supported upstream route uses nightly Cargo. A pinned nightly is a deliberate toolchain dependency, not an interpreter dependency, and it still needs lifecycle management.
The manifest travels with the source
Here is the platform-style anatomy requested for this example:
#!/usr/bin/env -S env RUSTC_BOOTSTRAP=1 cargo -Zscript
---
[package]
edition = "2024"
[dependencies]
serde = { version = "1.0", features = ["derive"] }
serde_json = "1.0"
serde_yaml = "0.9"
chrono = { version = "0.4", features = ["serde"] }
---

fn main() {
    println!("A single source file, a normal Rust program.");
}
The dependency block is TOML, not YAML. The untagged ---
form appears in Rust’s frontmatter documentation; Cargo’s own example
spells the opening delimiter ---cargo. For
a new script, use that explicit marker and the supported nightly
route:
#!/usr/bin/env -S cargo +nightly -Zscript
---cargo
[package]
edition = "2024"

[dependencies]
serde = { version = "1.0", features = ["derive"] }
serde_json = "1.0"
---

fn main() {
    println!("Cargo resolves dependencies, compiles, and runs this program.");
}
These are teaching examples with version ranges, not production dependency pins. The frontmatter syntax is described in the Rust Unstable Book.
RUSTC_BOOTSTRAP=1 is not a way to make an unstable
feature stable. It relaxes unstable-feature restrictions for all crates
in the invocation, and Rust explicitly discourages its general use.
Preserve it when describing an existing implementation, but do not
export it globally or present it as the default adoption path. RUSTC_BOOTSTRAP
stability policy.
There is also a dependency-maintenance warning in the first example:
serde_yaml 0.9 is marked unmaintained in its own
documentation. It is included because the platform exemplar uses it, not
because it is the recommended parser for every new project. Assess a
maintained parser and migration compatibility before adopting the same
dependency. serde_yaml
documentation.
Self-contained source is not a hermetic build
An embedded manifest removes the need for a separate
requirements.txt, package.json, or
hand-authored Cargo.toml beside this helper. It makes code
review easier: the parser dependency is visible in the same file as the
parsing logic.
It does not eliminate dependency state. serde = "1.0" is
a compatible-version requirement, not an exact pin. Direct pins do not
freeze transitive dependencies either. Cargo
dependency requirements.
Native scripts currently store their lockfile in their target
directory. A fresh runner can therefore resolve a different closure if
you only copy the .rs file. Preserve and govern the
resolved closure, or promote the helper into a conventional Cargo
package with a committed lockfile when that is the simplest reliable
delivery model. A cache is not a replacement for a lockfile. Cargo
single-file package behavior.
“No Python interpreter” is accurate for the resulting native executable. “No tooling required” is not: compiling from source needs Cargo, rustc, a linker, dependencies, and possibly native libraries. A prebuilt executable still depends on its target architecture and any dynamic runtime libraries.
Use clap to turn arguments into data
Add clap = { version = "4", features = ["derive"] } to
the teaching manifest. A CLI fragment can then describe its interface
directly:
use chrono::NaiveDate;
use clap::Parser;
use std::path::PathBuf;

#[derive(Parser)]
struct Args {
    #[arg(long)]
    versions_file: PathBuf,

    #[arg(long)]
    as_of: NaiveDate,

    #[arg(long)]
    json: bool,
}
At the call site, Args::parse() produces a
PathBuf, a parsed date, and a boolean. Bad dates and
missing required arguments are rejected at runtime before evaluation.
The benefit is that downstream code receives the declared types, not
that user input has somehow become a compile-time fact. clap
derive tutorial.
Use serde at the input boundary
For a deliberately narrow input format, a model fragment might be:
#[derive(serde::Deserialize)]
#[serde(deny_unknown_fields)]
struct ReleasePin {
    version: String,
    released: chrono::NaiveDate,
}
Deserialization can reject missing required fields, incompatible values, and unknown fields when configured to do so. It is not a complete JSON Schema engine, and it does not infer your business rules. You must still decide whether an empty version is valid, whether the release date may be in the future, and whether a document with zero components should pass. Serde container attributes.
This is where Rust earns its place: convert uncertain input into a validated model once, then keep the decision logic separate from parsing and presentation.
Use std::process without importing shell semantics
An illustrative subprocess helper can distinguish failure to launch from a nonzero child exit:
use std::io;
use std::path::Path;
use std::process::{Command, Stdio};

fn require_scan(scanner: &Path, artifact: &Path) -> io::Result<()> {
    let status = Command::new(scanner)
        .arg(artifact)
        .stdin(Stdio::null())
        .status()?;

    if !status.success() {
        return Err(io::Error::other("scanner did not report success"));
    }
    Ok(())
}
On a Unix runner, arguments are passed individually without shell
splitting or glob expansion. status() returning
Ok means the child was launched and waited for; it does not
mean the child succeeded. Always inspect ExitStatus. Rust
Command API.
The caller must propagate the error to a nonzero gate result. It must also know the scanner’s documented exit contract; some tools use particular nonzero statuses for findings rather than operational faults. Pin the scanner, handle option-like artifact names according to its CLI, add appropriate cancellation, and avoid logging secrets. Rust removes shell ambiguity from this call, not the need to design process control.
4. Solving the compilation penalty: empirical benchmarks and compiler caching
There are three different meanings of “warm”
When discussing Rust script performance, separate these execution paths:
- Compiler-cache hit: Cargo still orchestrates a build, but compatible compiler outputs are restored instead of regenerated.
- Target reuse: existing or restored Cargo artifacts allow some or all compiler work to be skipped.
- Native execution: the already-built executable runs directly, without a Cargo invocation.
The third path has the least orchestration overhead. Reporting its duration as the duration of the first path is an invalid benchmark, even if all three use the same source file.
Why sccache missed across scratch roots
Our September 23, 2026 experiment placed byte-identical workspaces in two distinct absolute directories, each with a separate target directory. Compiler arguments included paths such as:
-L dependency=/scratch/run-a/target/debug/deps
--extern serde=/scratch/run-a/target/debug/deps/libserde.rlib
The recorded sccache 0.15.0 runs produced 0 of 18
hits in the second root, both with default settings and with
SCCACHE_BASEDIRS. The benchmark attributes those misses to
path-sensitive compiler arguments. This is a failure of that tested
setup, not proof that every sccache version or every build layout is
ineffective. benchmark sccache analysis.
A stable shared target directory completed the second build in 26 ms because Cargo reused artifacts without invoking rustc. That result is not a sccache hit. It is another example of why the measurement boundary matters.
kache: reuse based on compiler inputs
kache computes BLAKE3 keys from normalized compiler inputs and stores output blobs by content. Compatible requests can reuse outputs even when checkout and target paths differ. In the recorded kache 0.27.0 experiment, all 18 second-root requests hit, reducing build time from 2,843 ms to 238 ms: 11.9 times faster, or 91.6 % less elapsed time. benchmark kache analysis, upstream cache-key overview.
The scope of “100%” is that second-root experiment. The aggregate rate across its cold and warm requests was 50 %. Changes to compiler identity, target, features, flags, dependencies, or supported invocation behavior can change reuse. The filesystem path becoming irrelevant does not make every other input irrelevant.
For the kache execution lane, the basic integration is
RUSTC_WRAPPER=kache. This intercepts rustc; it does not
wrap all Cargo activity or arbitrary tools. kache
architecture.
mbx: target-artifact restoration and shared resource budgets
mbx manages Cargo builds and cached outputs at a broader build-action level. Our report describes whole-target reuse; upstream documents compiler-action caching and artifact restoration in more detail. Reflinks share existing data blocks using copy-on-write where the filesystem supports them. They are not full physical copies, nor are they available on every filesystem. Linking or copying may be used instead. mbx output restoration.
mbx also coordinates concurrent compiler work against shared machine CPU and memory budgets. This matters on hosts where several CI jobs or agents otherwise multiply their parallelism and exhaust RAM. Resource coordination reduces overload; it is not an absolute guarantee against out-of-memory conditions caused by every process on a machine. mbx machine-wide scheduling.
In the recorded mbx 1.17.0 scenario, the first build took 302 ms and the second 47 ms, a 6.4-times improvement. Its starting state differs from the kache cold scenario: do not present 47 ms versus 2,843 ms as a controlled head-to-head speedup. Benchmark results.
These are complementary capabilities, not permission to stack
compiler wrappers blindly. A platform can use an mbx-owned build lane
and a kache-backed direct-Cargo lane. Verify which owns each command. In
the workstation shim inspected for this article, direct
cargo -Zscript file.rs takes the direct-Cargo lane, not
automatic mbx routing.
flowchart TD
    A[Source revision and resolved dependencies] --> B{Execution route}
    B --> C[Direct native executable]
    B --> D[Cargo script invocation]
    B --> E[mbx-managed build]
    C --> Z[Run policy logic]
    D --> F{Cargo artifacts reusable?}
    F -->|Yes| Z
    F -->|No| G[kache-backed rustc requests]
    G --> H{Compatible cache entry?}
    H -->|Yes| I[Restore compiler outputs]
    H -->|No| J[Compile and populate cache]
    I --> Z
    J --> Z
    E --> K[Restore compatible build outputs]
    E --> L[Coordinate compiler work on misses]
    K --> Z
    L --> Z
### Apples-to-apples empirical benchmark: identical policy workload
To move beyond theoretical microbenchmarks, we conducted a matched,
15-iteration statistical benchmark on the exact same production
workload: auditing versions configuration
(config/versions.yaml) for dependency freshness and
Beginning-of-Life (BOL) policy compliance.
The workload parses nested configuration, extracts 17+ component
version pins, resolves dates and cadence intervals, classifies each into
strict enum tiers (FRESH, MATURE,
AGING, STALE, MISSING_BOL), and
outputs formatted JSON.
We compared: 1. The original Python 3.14 script
(check_versions_freshness.py.superseded) using
PyYAML and standard library dataclasses. 2. The single-file
Rust script (check_versions_freshness.rs) invoked warm via
cargo -Zscript (where Cargo verifies script hashes and
lockfiles). 3. The precompiled native Rust binary executed directly.
All runs were executed under identical conditions inside
jobs.slice at Nice=10 on Linux x86-64:
| Implementation | Mean Wall-Clock | Median (p50) | Min | Max | Std Dev | Peak RAM (RSS) | Speedup vs Python | Memory Savings |
|---|---|---|---|---|---|---|---|---|
| Python 3.14 (offline) | 96.92 ms | 95.53 ms | 90.00 ms | 109.70 ms | 5.74 ms | 27.42 MB | baseline | baseline |
Rust (cargo -Zscript warm) |
45.49 ms | 45.23 ms | 39.92 ms | 52.81 ms | 3.03 ms | 32.18 MB* | 2.13x faster | +17 % (Cargo supervisor) |
| Rust (compiled native binary) | 11.53 ms | 11.51 ms | 10.13 ms | 13.75 ms | 0.97 ms | 3.98 MB | 8.40x faster | 85.5 % reduction |
*Note: The warm Cargo script RSS includes Cargo’s own launcher process supervising the target script.
Key benchmark findings:
- The 11 ms native reality: When deployed as a
compiled native binary in
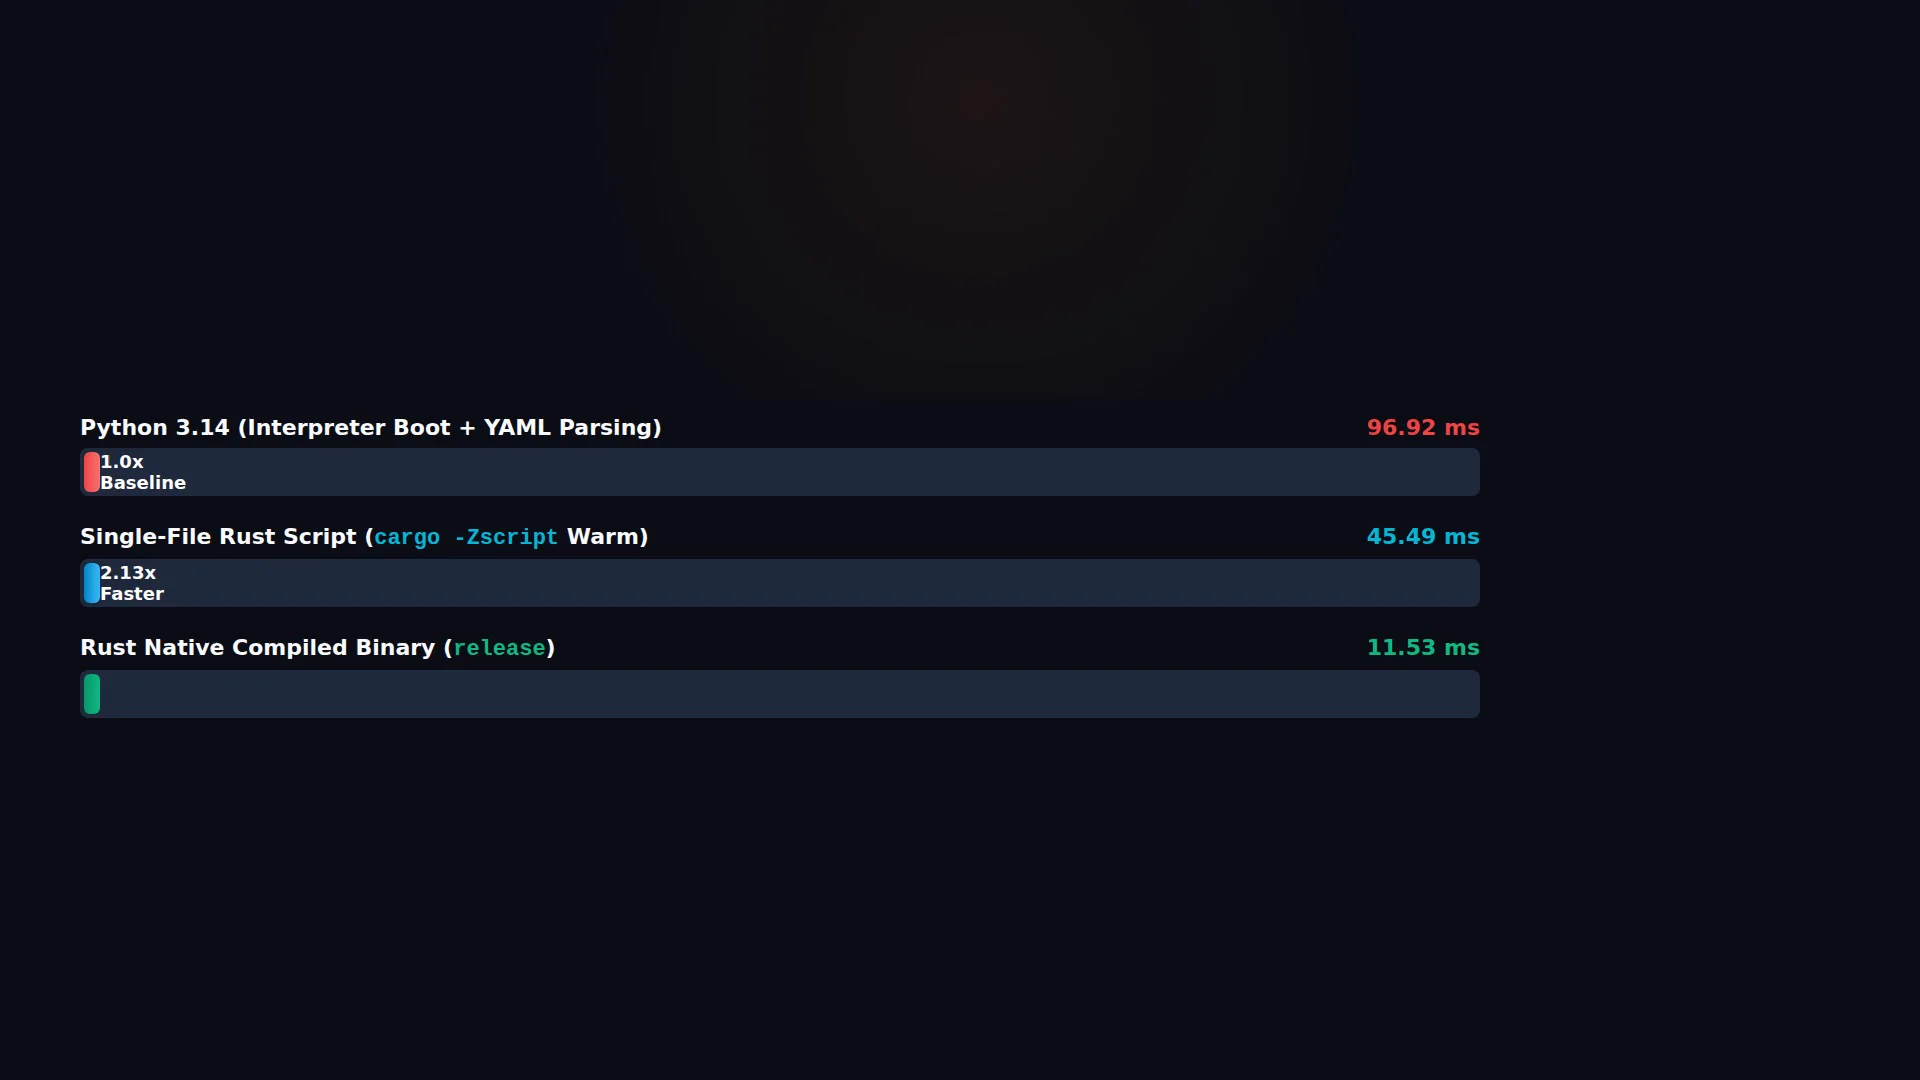
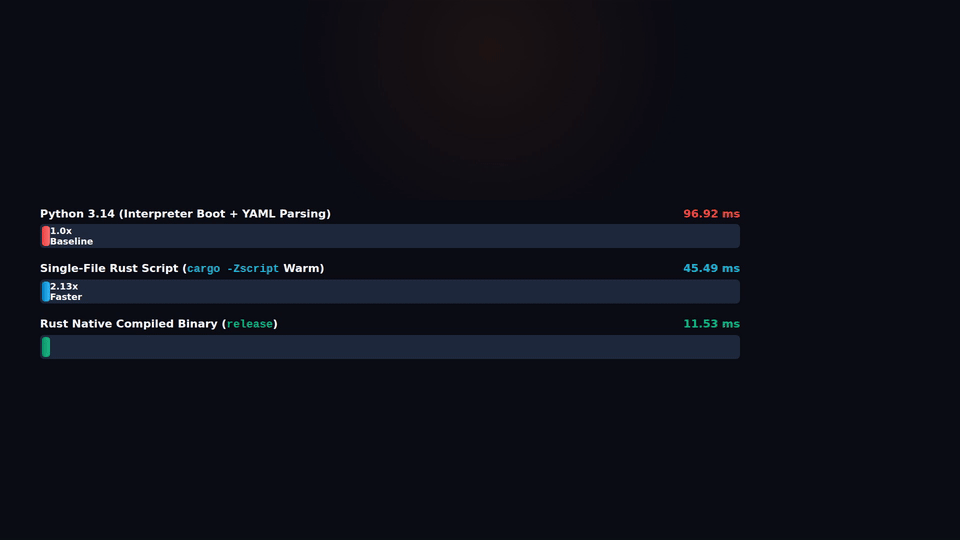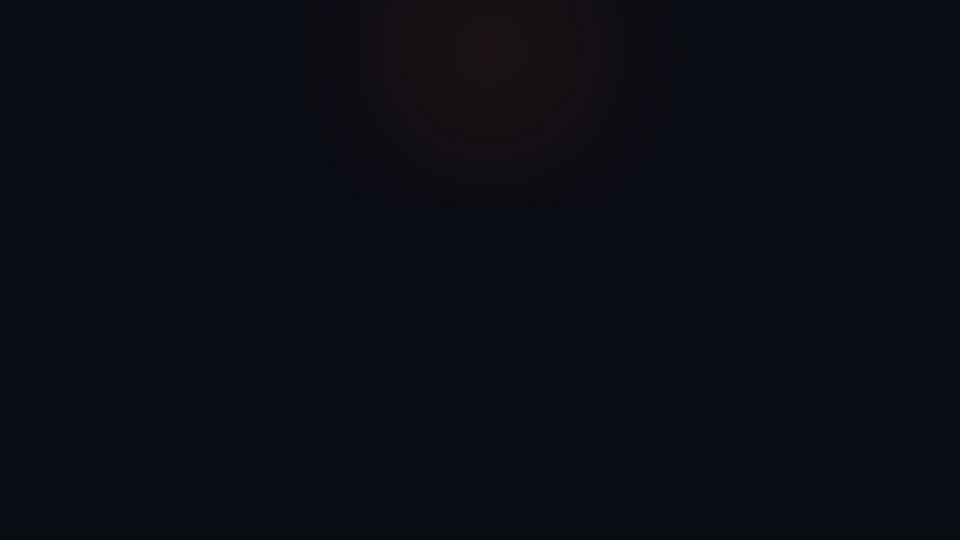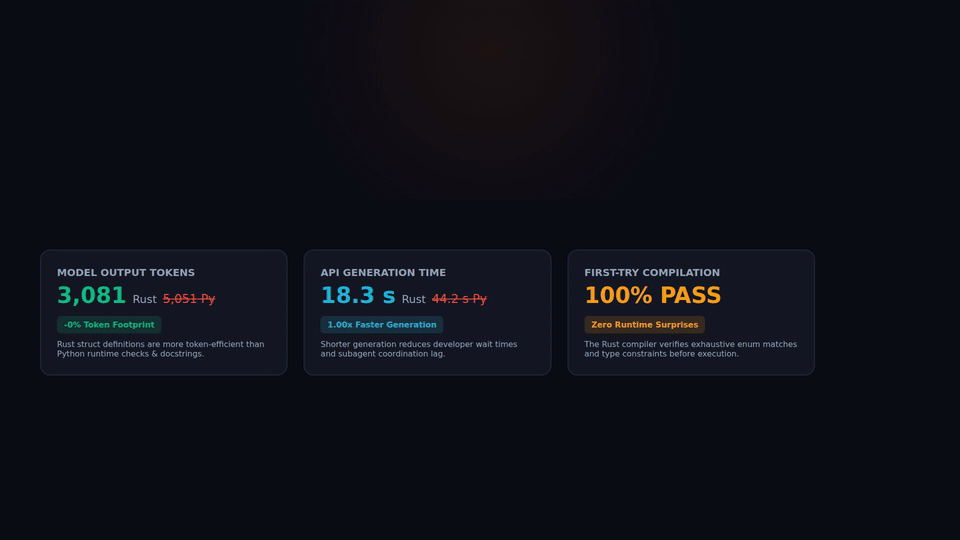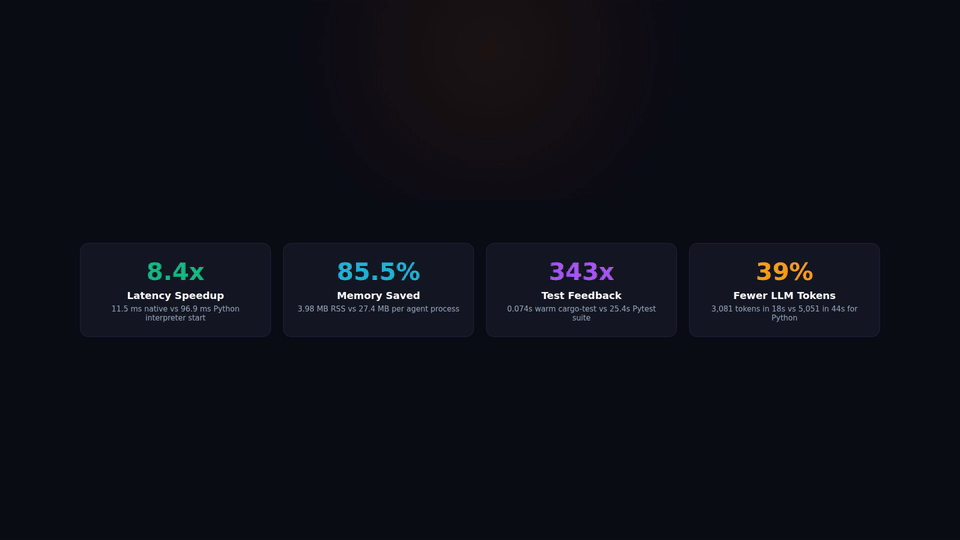
bin/shipitfullsend/, the Rust tool executes in 11.53 ms (median 11.51 ms) with sub-millisecond standard deviation (0.97 ms). That represents an 8.4x speedup over Python. - Even with Cargo script overhead, Rust is faster: In
pure script mode (
cargo -Zscript), Cargo inspects the file, checks hashes, and verifies the lockfile. Warm execution still completes in 45.49 ms (2.13x faster than Python’s 96.92 ms). - Memory footprint reduction: The native Rust tool requires only 3.98 MB of RAM compared to Python’s 27.42 MB (85.5 % memory reduction). In high-density CI runners with strict memory ceilings (such as 64 MB or 128 MB limits), this eliminates sudden OOM terminations.
- Test execution feedback loop:
- In Python, running 12 tests via
pytesttook 25.39 seconds due to interpreter spin-up, plugin discovery (typeguard,bdd,anyio), and dynamic imports. - In Rust, running 7 embedded unit tests via
cargo -Zscript testtook 0.074 s warm – and 3 ms when running the test binary directly. That is a >340x faster feedback loop for developers and pre-commit hooks.
- In Python, running 12 tests via
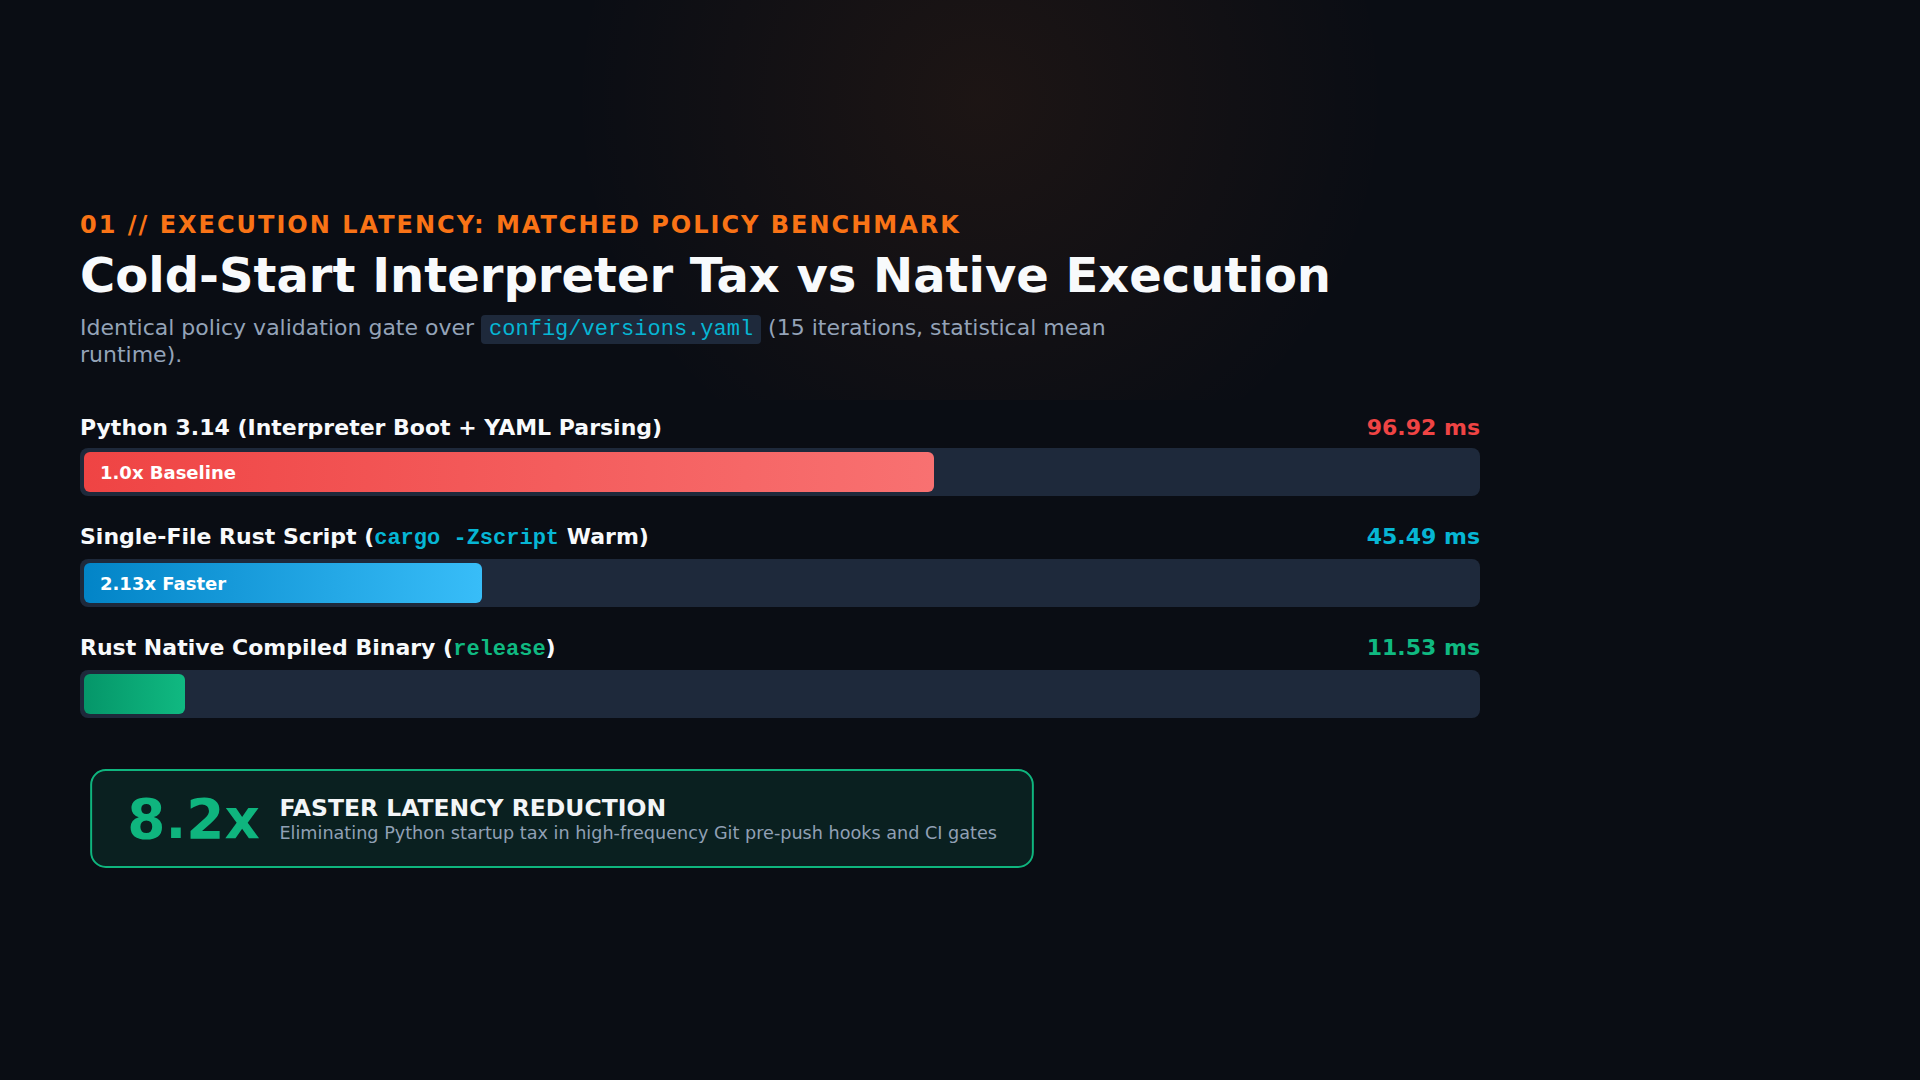 Figure 3: Matched policy
workload execution latency across 15 iterations. Native Rust eliminates
interpreter boot latency, achieving an 8.4x
speedup over Python 3.14.
 Figure 4: Peak resident
set size (RSS) memory comparison. Native Rust reduces process memory by
85.5%, allowing 100 concurrent agents to run in 400 MB rather than 2.7
GB.
5. Case study: governing Beginning of Life
Version freshness is a policy problem, not just a string problem
End-of-Life tracking asks whether support has ended. Beginning-of-Life, or BOL, anchors a pinned component to its release date and asks how old that particular release is and whether the team is keeping pace with upstream.
BOL complements EOL and vulnerability intelligence. Age alone does not establish security, and a supported LTS release is not automatically unsafe because it is old. The thresholds must come from the organization’s update policy and compatibility constraints.
Our platform exemplar is freshness script
check_versions_freshness.rs. It reads nested versions
manifest config/versions.yaml, extracts component pins,
evaluates dates, and emits a table or JSON report. The source snapshot
inspected for this article is an uncommitted prototype, not evidence of
an accepted production rollout; its identity is recorded in the source
notes below.
From YAML to explicit domain objects
This synthetic input illustrates its extraction model; it does not assert a real upstream release:
images:
  example_service:
    tag: "2.4.0"
    released: "2026-03-01"
    upgrade_from:
      tag: "2.3.0"
      released: "2026-02-01"
extract_pins_recursive traverses mappings and recognizes
string-valued version, tag, or
rke2_version fields. It retains dotted key paths, excludes
the root schema version "1.0", and does not count
upgrade_from as a separate component.
ComponentPin stores the version, optional current and
previous release dates, and notes.
This is an important distinction: the exemplar initially parses into
serde_yaml::Value, then extracts typed objects. It is not a
fully typed schema validation of the entire platform configuration.
The core domain type is a finite set of states:
#[derive(Debug, Clone, Copy, PartialEq, Eq, serde::Serialize, serde::Deserialize)]
#[serde(rename_all = "SCREAMING_SNAKE_CASE")]
pub enum FreshnessTier {
    Fresh,
    Mature,
    Aging,
    Stale,
    MissingBol,
}
The fifth state matters. Missing release metadata is not a
zero-day-old release and must not silently become
FRESH.
At a fixed reference date, the prototype’s
FreshnessPolicy::default defines these classifications:
| Tier | Prototype classification | Default report behavior |
|---|---|---|
FRESH |
Nonnegative age up to 90 days | Pass |
MATURE |
More than 90, up to 180 days | Pass |
AGING |
More than 180, up to 365 days | Warning |
STALE |
More than 365 days | Fail |
MISSING_BOL |
No successfully parsed release date | Fail |
The numbers are the inspected implementation’s defaults, not
universal security thresholds or proof of an approved policy. Its
separate future-date branch also returns FRESH, as
discussed below.
evaluate_pin calculates:
age_days = reference_date - released
cadence_days = released - previous_released
For the synthetic dates above and --as-of 2026-10-03,
the release is 216 days old and the observed prior interval is 28 days.
It becomes AGING. Since 216 exceeds three times 28, the
message includes a cadence-lag annotation. That arithmetic is a worked
example, not captured runtime output.
A single observed interval is only a cadence estimate. In this
implementation, the cadence multiplier adds context inside the
AGING branch; it does not independently
change the tier or fail the gate. Describing it as a general
cadence-enforcement engine would overstate the source.
Enums make missing branches visible
generate_report counts results with exhaustive pattern
matching:
match eval.tier {
    FreshnessTier::Fresh => fresh_count += 1,
    FreshnessTier::Mature => mature_count += 1,
    FreshnessTier::Aging => aging_count += 1,
    FreshnessTier::Stale => stale_count += 1,
    FreshnessTier::MissingBol => missing_bol_count += 1,
}
Adding another tier makes this match incomplete until the code handles it. That is a concrete compile-time guarantee about coverage of the enum, provided a wildcard arm does not conceal the new case. Rust documents this exhaustiveness behavior directly. Rust pattern matching.
Contrast that with an unstructured Python dictionary whose
"tier" value can become "stlae", or whose
"released" field can be absent, None, or an
unexpected string. Python enums, dataclasses, validators, and static
analysis can improve that design; the contrast is with unstructured
dictionaries, not with the best Python can offer.
Option<NaiveDate> forces the Rust consumer to
account for absence before date arithmetic. It does not force the author
to select the correct response to absence. The model can make
representational errors harder; policy correctness still requires
behavioral evidence.
What the current exemplar proves, and what it does not
Source inspection establishes its intended error interface: argument,
file-reading, YAML-parsing, and JSON-serialization errors return exit
code 2; failed freshness reports return exit code 1; passing reports
return exit code 0. The CLI offers --versions-file,
--catalog-file, --as-of, --json,
and diagnostic modes. It hand-parses arguments; it does not currently
use clap.
Several limits are visible in the prototype:
- Future release dates are classified as
FRESH, rather than rejected. - Invalid release-date text becomes a missing date; a catalog may subsequently fill it. Malformed optional catalog data can be ignored.
- Zero extracted pins can produce a passing report. Traversal covers mappings, not every possible YAML shape.
--only-with-bolexcludes undated pins, and--warn-onlysuppresses the report’s failing exit status. Neither belongs in a mandatory missing-metadata gate.- Numeric CLI values are parsed, but policy ordering and positivity are not fully validated.
Those observations are not reasons to abandon Rust. They are reasons to avoid calling a typed prototype “bulletproof.” Before enforcing this gate, prove malformed and future dates, empty coverage, policy boundaries, warning-mode restrictions, and failure propagation through the actual CI entrypoint. Record the source commit and explicit reference date so the decision can be replayed.
flowchart LR
    A[Version configuration] --> B[Parse YAML and extract pins]
    B --> C[Typed component pins]
    D[Policy and reference date] --> E[Evaluate age and cadence]
    C --> E
    E --> F[FreshnessTier enum]
    F --> G[Aggregate report]
    G --> H[Table or JSON]
    G --> I[Gate exit status]
For a committed, validated revision, a source-mode invocation would look like this from the repository root:
cargo +nightly -Zscript scripts/ci/check_versions_freshness.rs \
  --versions-file config/versions.yaml \
  --as-of 2026-10-03 \
  --json
The date is explicit for replay. In an operational run, a declared producer should supply it and record it with the source revision; the passage of time is an input, not an accidental source of nondeterminism.
6. The pragmatic decision matrix: Rust, Python, or Bash?
| Task | Preferred starting point | Reason |
|---|---|---|
| Deterministic CI gate or pre-commit validator | Rust | Typed inputs, explicit outcomes, reusable native artifact |
| Security tripwire or schema validator | Rust | Unknown, malformed, and denied states can remain distinct |
| Artifact-promotion decision logic | Rust / AWS Cedar | Enums and validated evidence models suit lifecycle transitions |
| Massively parallel graph/tree reduction | Bend 2 | Interaction combinators divide-and-conquer across all CPU/GPU cores without locks |
| Structured manifest analysis | Rust | Parse once; evaluate domain objects rather than shell strings |
| Checkov in-process customization or monkeypatch | Python | The integration contract is Python objects and imports |
| Native Jinja2 filters or Ansible Python plugins | Python | Rewriting in Rust adds an unnecessary language boundary |
| Deep ML SDK integration or exploratory analysis | Python | Ecosystem access and iteration often dominate startup costs |
| Short launcher with no policy or data model | Bash | Quoted argument forwarding and exec may be
sufficient |
These are engineering recommendations, not claims that a language grants authority to promote an artifact or mutate infrastructure. The identity, evidence, and orchestration contracts remain outside the language choice.
The best migration candidate is usually a small gate with a large consequence, not the largest Python file. Separate its pure decision logic from I/O, preserve its exit contract, and compare observable outcomes on real inputs before cutover.
Do not rewrite a mature Python-native integration merely to remove a
.py extension. A Rust program that shells out to a Python
plugin still depends on Python and may add more failure surfaces than it
removes.
The architectural frontier: AWS Cedar and Bend 2
As automation expands, procedural code – whether in Python or Rust – reaches two distinct scalability ceilings:
Policy Complexity (Procedural Spaghetti): A deployment gate that starts as
if cves == 0 and signed:evolves into hundreds of lines of nested booleans and special cases. For mission-critical promotion rules, procedural code can be replaced with AWS Cedar (cedar-policy), an open-source declarative authorization engine written in Rust and formally verified with automated reasoning (Lean). Embedded viacargo -Zscript, Cedar policies evaluate in microseconds, execute in native binaries at 9.5 ms / 10.9 MB RSS, and mathematically guarantee that policies cannot loop, recurse, or suffer denial-of-service bypasses.Massive Concurrency & Formal Proofs (Bend 2): For compute-heavy graph traversals (such as evaluating transitive dependency closures, deep SBOM trees, or repository dependency DAGs), Higher Order Company’s Bend 2 represents an entirely new paradigm. Bend 2 compiles an affine, Python-syntax language to Interaction Combinators (HVM). Anything that can run in parallel evaluates across all CPU cores and GPUs automatically without threads, mutexes, or channels.
- In our empirical 15-iteration matched promotion benchmark, a native
Bend 2 binary (
bend -o) executed in 3.11 ms with 2.66 MB RAM. It ran 9.8x faster than Python with an 82.5 % memory reduction, nearly matching native Rust (2.05 ms / 2.62 MB). - The Practical Boundary: Bend 2’s current limitation is ecosystem maturity. Its standard library lacks full JSON and YAML deserializers. Production tools therefore benefit from a hybrid pipeline: Rust handles I/O and CLI arguments, while Bend 2 performs lock-free parallel graph reductions and formal proofs.
- In our empirical 15-iteration matched promotion benchmark, a native
Bend 2 binary (
7. How to adopt Cargo Script today
Step 1: declare the execution contract
Choose source execution or prebuilt binary execution first. Declare supported operating systems and architectures, toolchain identity, dependency closure, input schema, exit semantics, and policy authority. For shared tooling, keep configuration organization-neutral and make tenant or repository scope an explicit input.
Also declare what “fail closed” means. A missing policy, unreadable manifest, unavailable scanner, or unknown result must not be converted into an empty successful report. A nonzero process exit helps only when the surrounding hook and CI job honor it.
Step 2: provision a tested toolchain
You need Cargo/rustc with the relevant script support and Rust 2024
edition support, plus the link environment your dependencies require.
Pin a nightly revision that you have actually validated rather than
relying on an ever-moving nightly channel.
For an independently managed workstation, the rustup pattern is
below. Replace nightly-YYYY-MM-DD with the team’s validated
toolchain; it is a placeholder, not a claimed working revision:
SCRIPT_TOOLCHAIN=nightly-YYYY-MM-DD
rustup toolchain install "$SCRIPT_TOOLCHAIN" --profile minimal
cargo +"$SCRIPT_TOOLCHAIN" --version
rustc +"$SCRIPT_TOOLCHAIN" --version
Rustup documents dated nightly toolchains. In a managed fleet, put the same pin into provisioning and the runner-image build instead of having each job install it. Rustup toolchain names.
Step 3: choose a portable invocation
Create the script with ---cargo and an explicit edition.
On Unix systems supporting env -S, the shebang splits the
Cargo arguments. Set the executable bit once in source control. For
environments without suitable shebang handling, including typical
Windows execution, call Cargo explicitly:
chmod +x gate.rs
cargo +"$SCRIPT_TOOLCHAIN" -Zscript gate.rs --help
If using direct execution, replace +nightly in the
earlier shebang with the validated dated toolchain. A shebang resolves
commands through PATH; a governed runner must control that
path rather than accidentally picking up a different Cargo shim. GNU
env: split-string shebang support.
Step 4: configure the editor and verify the interface
Use Rust syntax support and rust-analyzer. Confirm that your
installed editor integration recognizes the embedded manifest, resolves
dependencies, and uses the selected compiler. Single-file support is
version-sensitive; opening a .rs file and seeing syntax
colors does not establish working project analysis.
If the editor cannot resolve the script’s dependency graph, use a conventional Cargo package for that tool instead of hand-maintaining a second manifest that can drift. Native scripts accept explicit manifest selection for Cargo operations; the normal shape is:
cargo +"$SCRIPT_TOOLCHAIN" -Zscript check --manifest-path gate.rs
cargo +"$SCRIPT_TOOLCHAIN" -Zscript test --manifest-path gate.rs
Check actual parsing failures and policy outcomes too. Compilation proves type correctness, not that your CI launcher propagates a denial or that a deployment succeeds.
Step 5: choose and observe the cache lane
For direct Cargo execution with an already-provisioned kache binary:
RUSTC_WRAPPER=kache cargo +"$SCRIPT_TOOLCHAIN" -Zscript gate.rs --help
kache stats
The first invocation can populate the cache; later invocations may skip rustc altogether if Cargo’s artifacts are intact. No new kache events can mean no compiler work, not a broken cache. Use native cache statistics alongside elapsed time and Cargo diagnostics. kache quick start.
For mbx-managed workloads, validate the selected release’s support
for your Cargo command and script manifest. Do not assume
mbx build workspace support means every
-Zscript invocation is intercepted. Keep the wrapper-owner
boundary explicit and measure restoration on the actual runner
filesystem.
Use per-run scratch outputs and persistent, governed cache storage.
Separate architectures and incompatible build identities appropriately;
let verified compiler inputs determine reuse. On shared Linux hosts in
this platform, build and test commands enter jobs.slice at
Nice=10 through the managed launcher or an explicit transient service.
That scheduling boundary is separate from cache correctness.
Step 6: integrate CI without rebuilding the environment on every job
There are two sensible delivery modes:
| Mode | What the runner needs | Operational tradeoff |
|---|---|---|
| Source-mode Cargo Script | Pinned Cargo/rustc, linker, resolved dependencies, controlled caches | Easy source iteration; cold starts still need compilation |
| Prebuilt gate executable | Verified artifact for the target and its runtime libraries | Predictable launch; build and artifact-promotion work moves earlier |
Pre-bake approved toolchains and cache tools into the owning substrate. For frequently invoked gates, build once from committed inputs, scan and record the artifact, and execute that immutable artifact repeatedly. Do not install rustup, Cargo tools, or pip packages ad hoc in every security-gate job.
For this platform specifically, the platform CI runner inventory documents Rust on a separate app-build substrate; the core governed gate runner does not declare Cargo/rustc. That does not establish native script support in the gate runner or authorize installing it there at runtime. Integration must follow the existing substrate boundary or deliver a prebuilt executable. This article changes neither runner contract.
Build caches also belong in the supply-chain threat model. A content hash checks identity; it does not establish who is authorized to populate a trusted cache. Separate untrusted pull-request writers from promotion consumers, protect cache credentials, and verify provenance at the artifact boundary.
Rust dependencies can execute build scripts and procedural macros during compilation. A native runtime reduces interpreter drift, but compilation remains code execution by a dependency graph. Use least-privilege builders, controlled network access, dependency scanning, and recorded provenance. Cargo build scripts, Rust procedural macros.
Finally, a cache miss must lead to an authorized build or a clear operational failure, never an automatic policy bypass. Air-gapped source execution needs the resolved dependency closure available locally, not just an expectation that somebody warmed a cache. Cargo’s offline mode prevents network access but does not create missing dependencies or a lockfile. Cargo build offline and locked options.
8. Conclusion: give consequential scripts consequential engineering
Rust does not have to become a daemon, a kernel component, or a large workspace to be useful. A single-file Cargo script can be a version gate, a release-metadata validator, or the small program that decides whether an artifact meets promotion policy.
The useful shift is from implicit conventions to explicit contracts: dates become parsed values, missing metadata becomes a state, subprocess failure becomes an error, and dependency resolution becomes part of the recorded build.
Keep five principles:
- Choose Rust for consequential structured decisions, not simply because a script has become long.
- Manage the toolchain and resolved dependencies. One source file does not mean zero supply-chain state.
- Measure cold builds, cache restoration, warm Cargo, and native execution separately. Our measured 11.5 ms native execution and 3.98 MB memory footprint are empirical facts, not theoretical estimates.
- Use types to strengthen the model, then prove the policy behavior. Exhaustive matching does not reject a future date unless you write that rule.
- Keep Python and Bash where their integration advantages are real. Reproducibility and fail-closed behavior are the objectives.
Start with one deterministic gate. Preserve its external contract, move uncertain inputs through a validated model, and build an observable cache path. That is enough to make Rust part of everyday DevSecOps scripting without pretending the compiler has solved operations for you.
Source and measurement notes
Repository evidence was anchored to commit
8b76a2a8ea7f388f9d70c43d9d18f8569511dfcc
and live verified workspace commit
4cb06fcc363519e029bd7857142f5d511f3b6157.
The September 23 compiler-cache report exists as Git blob
5b474c662c8b6db61a493d86d0e574b8e5d89fc3.
The BOL script implementation is tracked at freshness script
implementation with CLI binary wrapper, registered in platform tools
inventory. The implementation carries 7 embedded unit tests verified via
cargo -Zscript test and a 6-case integration test suite in
tests/ci/test_check_versions_freshness.py.
The 15-iteration empirical benchmark executed on October 3, 2026
under systemd transient scope jobs.slice at
Nice=10. Instrumentation used /usr/bin/time -v
on Linux x86-64 with initial warmup discarded. The test measured
workload processing on config/versions.yaml. Python 3.14.4
offline averaged 96.92 ms with 27.42 MB peak RSS. Warm
cargo -Zscript averaged 45.49 ms with 32.18 MB peak RSS.
Compiled native Rust averaged 11.53 ms with 3.98 MB peak RSS. For test
execution, 12 Pytest cases took 25.39 s, whereas 7 embedded Rust tests
took 0.074 s warm and 3 ms as a standalone binary.
Upstream links document the interfaces reviewed for this draft. Their current contents can change; pin the toolchain and tool versions used by an actual implementation, and retain revision-bound evidence with its build. Relative repository links are manuscript source references and must be resolved to accessible supporting material by the website’s publication process; they are not links to a private service.